Cheap decisions, expensive assumptions: Jev, Laya and Claude routing
Jev and Laya can cut the cost of bounded decisions. Choosing a Claude model for a coding task still requires relevant, current project context.
“Change the project’s language.”
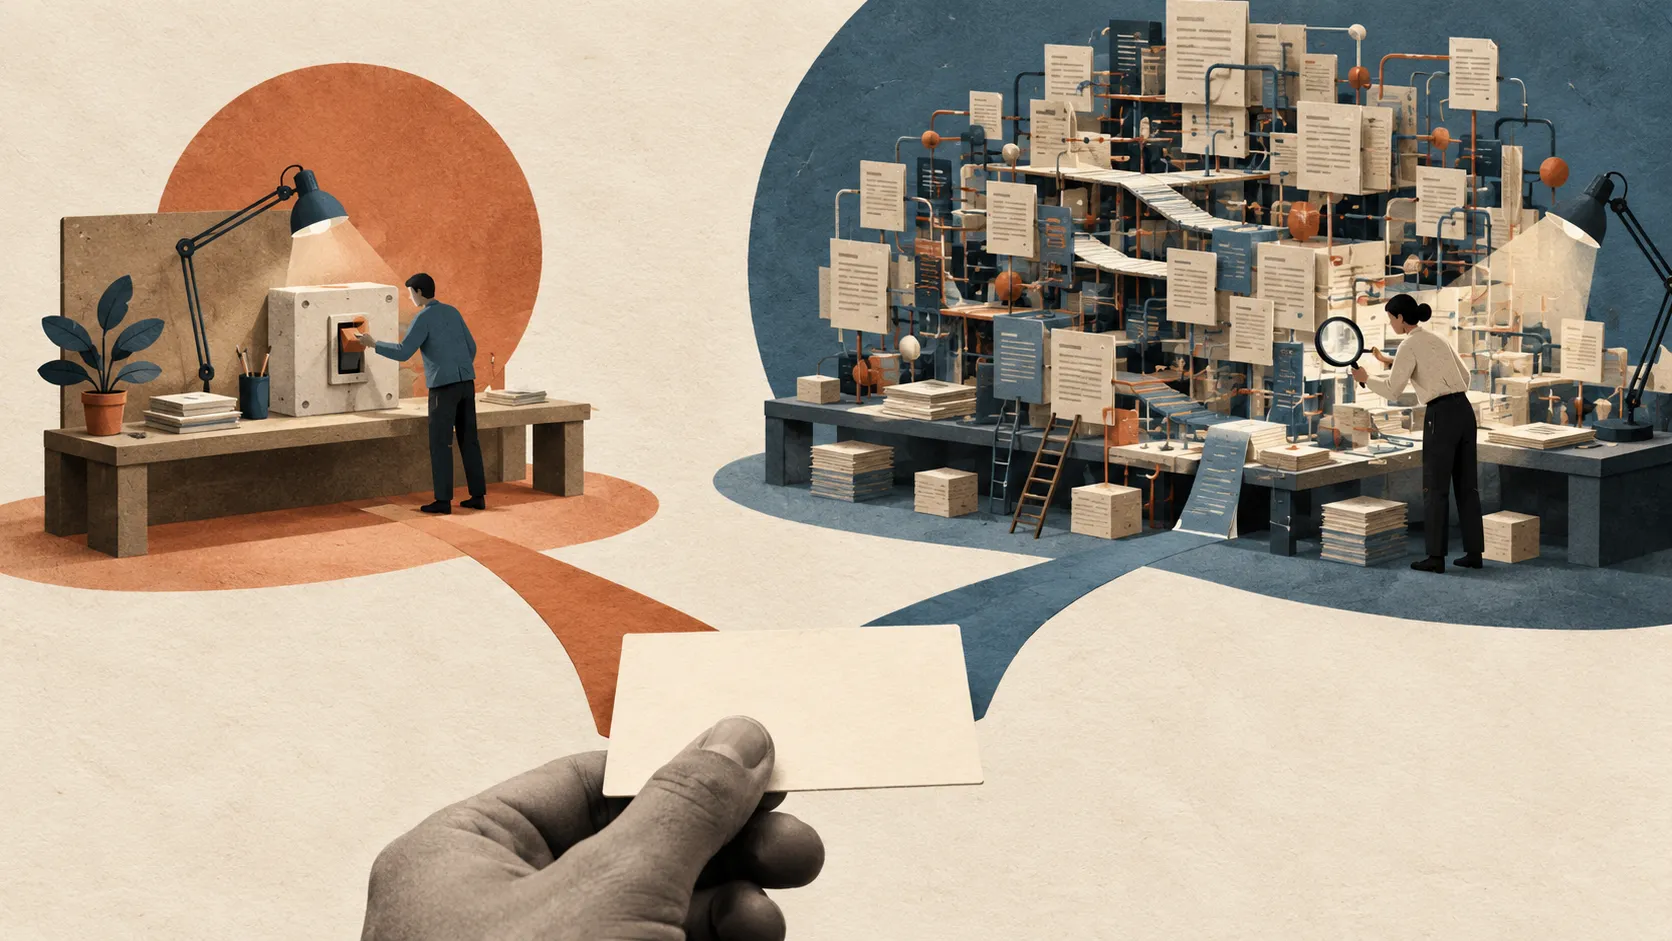
In one application, switching the interface language means changing a configuration line. In another, it means finding thousands of strings, adding localization, adapting layouts and checking everything again. If the request refers to the programming language, it might mean a migration.
One line or 3,000: the same short request can hide very different work. These are hypothetical examples, and line count is no measure of difficulty. What matters is that the prompt does not reveal the project’s actual requirements.
That is where I would draw a boundary around cheap decision models. Jev and Laya offer a useful way to reduce the cost of small judgments inside software. Using them to choose a Claude model for an entire coding task requires a much stronger understanding of what that task involves.
Where a small decision model earns its place
Jev returns choices, scores and yes/no probabilities from a supplied state. Its documentation recommends narrow questions whose answers are combined in code. Laya provides similar typed decisions. Jev introduction, Laya model card
Consider a support system that repeatedly asks an expensive model whether a ticket concerns billing or whether a customer sounds frustrated. Those judgments are candidates for a cheaper decision layer, provided its accuracy is measured on real messages.
| Decision | Relevant input | Possible benefit |
|---|---|---|
| Identify intent or sentiment | Message and relevant earlier exchanges | Avoid a larger classification call |
| Choose whether to consult internal documents | Request and descriptions of available sources | Avoid unnecessary retrieval |
| Select a known tool | Request, candidate tools and required identifiers | Dispatch a bounded workflow |
| Filter RAG passages | Question and retrieved passages | Reduce the answering model’s input |
| Select a model tier | Task evidence and measured results for each tier | Reserve expensive execution for suitable cases |
These are design opportunities, not performance promises. RAG means retrieving relevant material before answering. A request can need both documents and live tools: “check my order and explain the refund policy” is a straightforward example.
TypeSafe publishes examples of passage filtering and choosing functions with arguments drawn from fixed lists. RAG filtering, Function calling
Choosing a function still leaves the application responsible for validation, permissions, execution and errors. Producing an arbitrary query or implementing a migration requires further work.
Recognizing the request does not establish its difficulty
A classifier can correctly identify a language change as a software task. To decide which Claude model should implement it, the system may need to inspect the repository: existing translations, dependencies, tests, deployment assumptions and previous decisions.
The same problem appears with “fix authentication.” The change might be a missing setting, or a problem spanning sessions, permissions and data storage. Without that evidence, a difficulty label is an estimate based on incomplete information.
During execution, the evidence changes. A failed check exposes another dependency. A tool returns something unexpected. A change that looked local affects another service. Routing based only on the opening sentence cannot account for facts discovered later.
These models have context; supplying the right context is the challenge
It would be inaccurate to say Jev and Laya cannot read context. Jev 1.13 permits 64k tokens per request, with a separate 32k limit for state plus the longest question. Laya’s English checkpoint defaults to 512 tokens; its multilingual checkpoint defaults to 1,024 and supports up to 8,192. Jev limits, Laya limits
A window is capacity, not guaranteed understanding. TypeSafe reports difficulties with multiple reasoning hops and irrelevant detail in large states. Laya documents confidently wrong predictions in some settings and the need to validate probabilities on your own data. Jev failure modes, Laya limitations
“Do the same for the other account” requires earlier context. A router needs to know the operation, the account and whether the previous attempt succeeded. A summary can preserve those facts, but it can also omit them or become outdated. Someone must build and maintain that state, and that work belongs in the cost calculation.
Route bounded decisions, then reassess with evidence
My proposal is to give the decision layer a precise responsibility. Use ordinary code for exact rules, a decision model for semantic classification, and a coding agent for project investigation and implementation.
When difficulty depends on repository details, inspect first. Route using the findings, include an uncertain outcome, and allow escalation when subsequent evidence changes the task. Confidence thresholds should be chosen from observed errors; missing context and unfamiliar requests deserve separate checks.
This can support routing within a Claude workflow. It does not establish that Jev or Laya is a dependable universal router for Claude. The usefulness of the router depends on the evidence supplied and the decisions it has actually been evaluated to make.
Count savings across the completed job
Suppose an existing classification call costs $0.002. A replacement costs $0.00002, but 20% of requests still need the original call. The average becomes $0.00042: a 79% saving for that classification stage, before error costs. These are invented amounts to explain the calculation, not a benchmark or provider quotation.
If classification accounts for only 5% of the bill, that saving reduces the total by about 3.95%, assuming everything else stays the same. Larger gains require avoiding expensive downstream work or reducing its input.
At publication, Jev lists $0.042 per million input tokens, with output free. Self-hosted Laya still incurs compute and operating costs. Jev pricing
Measure cost per successfully completed task, including investigation, retries and escalation. A cheap routing error can lead to an expensive recovery.
I would start with intent, sentiment, passage relevance and known workflows. For a coding agent, I would keep routing responsive to the project as it is discovered. A short request can lead to a one-line change or a substantial migration. The system needs enough evidence to tell which job it is accepting.